The time is 3:27 am on the East Coast as I write this. It's Sunday, I have work tomorrow morning.
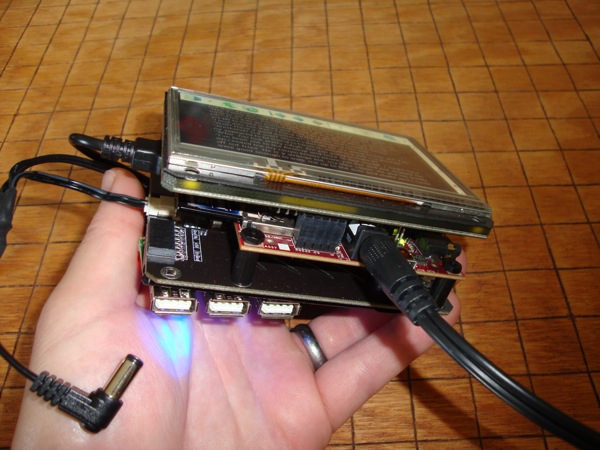
I'm happy to say... Android has now officially been cracked onto the Beagle GadgetPack. Chris and I just finished hacking it onto the BeagleBoard, with a fully-integrated touchscreen OLED screen, overlay, and interface at the driver level to the BeagleTouch.
It connects to the internet.
It loads webpages, it runs scripts.
It reads and interfaces to sensors.
The touchscreen supports drag, drag and drop, sliding, scrolling, and gesturing.
It can download and run native Android APK files off of Open APK app stores.
It even runs the SL4A rapid prototyping environment that is scriptable in Perl and Python.
This was no easy task. Nick, Will, Chris, Mike all helped here and there with driver help and ideas for how to compile around the early driver problems. Thanks to the TI guys (esp. Gerald!), and the Google Groups community too for their help... and for the guys at embinux.org for a good starting point reference. And of course some special help from Google themselves (names will remain anonymous because I'd hate to see someone lose their job for supporting a hacker like me)... who came in at the last minute to help me crack open the driver access level, which allowed me to make a user-space display driver to the BeagleTouch... FROM SCRATCH.
Now the most important part of all of this is the question I got from Jake, when I talked to him 3 weeks ago: why?
Because I'm sick of the iPad. Every time you go into Starbucks, you see someone digitally frolicking around on their apps, clickety clacking around with glee, pinching and spinning their fingers around a million times just to do what you used to be able to do with CNTRL-+ or CNTRL-- to zoom in and out just as quickly, all the while being wholly restricted and unable to compile any of their own apps natively, and god forbid trying to access the driver level.
The problem is simple: I am fundamentally against the entire principle and idea of the phrase, "there's an app for that(TM)." (Are you serious?!?! I have to put a "Trademark" on that?!?) I think that little phrase is endemic of everything that's going wrong with the hacker world today. It symbolizes the end of an era. It is the antithesis of open, and the optimum of control and limitation.
I don't want an app for that. I want a programming language and access to some low level OS function for that.
I'm fighting back, and this Android hack is the first step in the war. The problem with the philosophy of "there's an app for that" is that it's training the new up and coming programmers and would-be hackers and developers that if you want some hitherto unavailable functionality for your device, you should go onto a tightly controlled ecosystem of apps (iTunes app store), and pay money for a limited, controlled, censored, channel monitored, Apple-sanctioned little app that took WAY too long to write because the darn specs are undocumented.
No thank you. I want to help teach, train, and motivate a new breed of far more open sourced and efficient hardware hackers...
Apple is going to lose. Because hackers are going to use the platform that is the most extensible, most hackable, and most fun to use. Programming the iPod and iPad and app store-compatible apps is an exercise in painful, torturous sacrifice. You start out development thinking you want to build a simple little functioning app. Then you find out, function by function, that Apple has restricted that functionality to a mere fragment of it's former self. Useless!
Android is where it's at. You get driver control if you need it, you have a multitude of programming languages, an Open Source app distribution channel, and raw sensor channels for interfacing with all kinds of sensors (stay tuned for some hacks on this to come). Android is literally the perfect rapid prototyping platform. It is just high level enough to be efficient, it's just low level enough to enable embedded applications development. And it's Open Source, so if you need to, you can just recompile the whole darn thing from scratch yourself if you want to.
And that's powerful. In the coming weeks, I'm going to do my best to integrate open source hardware and open source software together, using this newly cracked Android Gadget as my platform... bring it on!
Monday, October 18, 2010
Saturday, October 16, 2010
How to turn a Beagle GadgetPack into a digital ASCII bunsen burner
Time for a silly application of modularity... for no intent or purpose, simply demonstrating a Matrix-esque special effect on the front of the BeagleTouch module, running aalib's ridiculously cool aafire app.

Will and Chris put together a pretty cool little auto-loading script, and made sure all the aalib libraries were in place (which they were), and it just worked. The cool part is mostly how fast the demo seems to run...
Now time for the good part... as every hacker knows, the food pyramid contains 3 essential foods:
Yes, they are listed in that order because that is roughly how they stack up in order of mass consumed by me per week. I mean seriously, where would Linux virtual memory, Android's driver subsystem, and Ruby on Rails be, if not for these 3 food groups? I can personally attest to consuming my fair share... not because I particularly like the taste of any of them, but simply because generations of hackers before me have lived on exactly this, and who am I to challenge tradition? (This is getting ridiculous, I know). Many books have been written about programmer and hacker productivity, methods of development, etc. but I might argue that Red Bull, Pop Tarts, and Raman are a radically under-researched productivity tool.
But suffice to say, a digital ASCII blue fire bunsen burner - although non-functional - sure *looks* cool as heck underneath a can of Red Bull, doesn't it? It must be doing something... I swear it tasted better than my not-so-highly scientifically isolated placebo trial.
:-)
Ok, here's how to get it up and running on the Beagle Embedded GadgetPack:
Open up a terminal like xterm using the keyboard connected to the USB port on the side of the GadgetPack.
Then, either download this package onto the SD card, or if you have the Wifi Module or Ethernet Module, you can type this directly onto the command to download aalib:
wget http://sourceforge.net/projects/aa-project/files/aa-lib/1.2/aalib-1.2.tar.gz
Untar the archive:
tar xvf aalib-1.2.tar.gz
Move to the directory:
cd aalib-1.2
Run this command to configure:
./configure --host=localhost
Then compile the source code:
make
make install
And then run, sit back, and enjoy the digital fire that neither keeps you warm, *nor* cools you down, so at least it's not a negative fire, or put in other terms, at least the correlation coefficient between this digital bunsen burner and utility is not negative (R is at worst 0, so ha!):
export DISPLAY=:0.0
xterm -fg red -bg black -e "./aafire"
Voila!
For more pictures of the ASCII burner, I've uploaded some high res shots at flickr...
Will and Chris put together a pretty cool little auto-loading script, and made sure all the aalib libraries were in place (which they were), and it just worked. The cool part is mostly how fast the demo seems to run...
Now time for the good part... as every hacker knows, the food pyramid contains 3 essential foods:
Yes, they are listed in that order because that is roughly how they stack up in order of mass consumed by me per week. I mean seriously, where would Linux virtual memory, Android's driver subsystem, and Ruby on Rails be, if not for these 3 food groups? I can personally attest to consuming my fair share... not because I particularly like the taste of any of them, but simply because generations of hackers before me have lived on exactly this, and who am I to challenge tradition? (This is getting ridiculous, I know). Many books have been written about programmer and hacker productivity, methods of development, etc. but I might argue that Red Bull, Pop Tarts, and Raman are a radically under-researched productivity tool.
But suffice to say, a digital ASCII blue fire bunsen burner - although non-functional - sure *looks* cool as heck underneath a can of Red Bull, doesn't it? It must be doing something... I swear it tasted better than my not-so-highly scientifically isolated placebo trial.
:-)
Ok, here's how to get it up and running on the Beagle Embedded GadgetPack:
Open up a terminal like xterm using the keyboard connected to the USB port on the side of the GadgetPack.
Then, either download this package onto the SD card, or if you have the Wifi Module or Ethernet Module, you can type this directly onto the command to download aalib:
wget http://sourceforge.net/projects/aa-project/files/aa-lib/1.2/aalib-1.2.tar.gz
Untar the archive:
tar xvf aalib-1.2.tar.gz
Move to the directory:
cd aalib-1.2
Run this command to configure:
./configure --host=localhost
Then compile the source code:
make
make install
And then run, sit back, and enjoy the digital fire that neither keeps you warm, *nor* cools you down, so at least it's not a negative fire, or put in other terms, at least the correlation coefficient between this digital bunsen burner and utility is not negative (R is at worst 0, so ha!):
export DISPLAY=:0.0
xterm -fg red -bg black -e "./aafire"
Voila!
Labels:
Liquidware
Thursday, October 14, 2010
Maker Faire NYC Debrief
I now live in Boston. I used to live in New York. Which made it all the more ironic when it came time to travel down to NYC to attend Maker Faire with Justin, Francis, Will and Mike. As it turns out, the night before we all headed down there, the construction crews decided to tear up a portion of I-95, which naturally meant some lane closures.
Nothing pumps up the DIY hacker spirit like sitting in traffic for 5 hours staring at this picture from the Main Street Danbury blog:
Hmmm, hmmm... I feel like that red card is a lot like the feeling I get when the bootloader doesn't load on the flash ram chip on the topside of the BeagleBoard OMAP, and I have to solder in my own debug cables to test the signal pins to make sure they work. And that truck is like the weight in my arm after 2 hours of solid soldering... and the right hand lane is the re-routing schematic of envy... yes.
But once we got to Maker Faire, the situation changed dramatically (it did take about a 30 minute detoxing whereby we desensitized to the intense traffic around Brooklyn and Manhattan). And here we were, to the right, and next to Nate from Sparkfun... Here's Mike and Will getting swamped with questions :-)
I like to try to construct a pyramid of TouchShield Slide boxes just for kicks:
I walked around, and saw a few fun pictures. Like this one, which although looks fun to some, is not really my cup of spinning tea. The whole time I'd be thinking, I really hope those welding points worked on the central axis tower:
Here was a view from outside the master tent:


I want one of these so badly, it's not even funny. I imagine I could do home delivery of DIY kits throughout New England on something like this. Would it be more time intensive and more expensive than UPS or DHL? Yes. Would it be worth it to do spin out donuts in street and driveway on the way to hand delivering a package of Arduino and BeagleBoard modules? Absolutely.
Here's a picture of Francis showing off a few projects...
I put a few more pictures up on the Flickr page in the original resolution...
Nothing pumps up the DIY hacker spirit like sitting in traffic for 5 hours staring at this picture from the Main Street Danbury blog:
Hmmm, hmmm... I feel like that red card is a lot like the feeling I get when the bootloader doesn't load on the flash ram chip on the topside of the BeagleBoard OMAP, and I have to solder in my own debug cables to test the signal pins to make sure they work. And that truck is like the weight in my arm after 2 hours of solid soldering... and the right hand lane is the re-routing schematic of envy... yes.
But once we got to Maker Faire, the situation changed dramatically (it did take about a 30 minute detoxing whereby we desensitized to the intense traffic around Brooklyn and Manhattan). And here we were, to the right, and next to Nate from Sparkfun... Here's Mike and Will getting swamped with questions :-)
I like to try to construct a pyramid of TouchShield Slide boxes just for kicks:
I walked around, and saw a few fun pictures. Like this one, which although looks fun to some, is not really my cup of spinning tea. The whole time I'd be thinking, I really hope those welding points worked on the central axis tower:
Here was a view from outside the master tent:
I try to show up with as many projects as possible, and here are a few using the BeagleBoard and BeagleTouch:
I want one of these so badly, it's not even funny. I imagine I could do home delivery of DIY kits throughout New England on something like this. Would it be more time intensive and more expensive than UPS or DHL? Yes. Would it be worth it to do spin out donuts in street and driveway on the way to hand delivering a package of Arduino and BeagleBoard modules? Absolutely.
It only occurred to me after that this is a picture of everyone systematically walking away from me. The three folks on the left actually turned around right after this and started walking away too. Must have been something I said...
Here's a picture of Francis showing off a few projects...
I put a few more pictures up on the Flickr page in the original resolution...
Labels:
Liquidware
Saturday, October 2, 2010
Open Source Hardware Summit Debrief
A week ago I went down to NYC and spent a few hours at the Open Source Hardware Summit. I sat on a panel and discussed with a number of pretty smart individuals, the merits of Open Source legal constructs and what Open Source Hardware is and isn't. A big, heart-felt thank you from me goes out to the organizers, sponsors, and creators of the summit.
Of course, there were so many more thoughts running through my mind than I could possibly share with the group, and I didn't want to monopolize the speaking time, so I took lots of notes. Here are a few of the notes I jotted down:
-What is the relationship between open source rights and intellectual property protection provided by the government?
-Is an open source design patentable? Is it copyrightable? Is it trademarkable?
-Open source hardware designs are getting licensed to hardware builders for rates around 5-10%, yet patented technologies have concepts like compulsory rates of 3%. Does that mean that patented designs might actually be cheaper than open source?
-Does an open source design have to be recursive and/or fractal? Can you have an open source design that uses proprietary integrated circuit chips? Can you use an open source circuit in a proprietary, closed device?
-Many of the successful open source hardware projects have in common that they rigorously protect one aspect of their business: arduino gives away the board but keeps the brand and trademark, beagleboard gives away the design by keeps the chip gate array design, bug labs gives away the schematics but restricts the inter-module snap-connect interface, liquidware gives away the hardware at cost, but keeps the analytical algorithms (e.g. you can buy a "military grade" IXM, but you can't get the code that turns it into a --CLASSIFIED--) Exactly :-)
-What do you use to base an open source hardware license on? Does it start from a contract that restricts freedom to operate, and use, or does it look more like wills and testament document, where it gives away rights and freedoms?
-Is the goal of open source to provide freedoms? If so, why does it need a license or contract to restrict rights?
-What is the relationship between the drivers and motivators of hackers, and the objective of a license? Could you have had open source software without the GNU?
-What came first: the license, or open source code?
-What is the "source" part of open source hardware? Does hardware have a standard "source" (no)? How long will it take to get there (a long time)?
All in all, I think - as always - I'm left with many more questions than answers, but I think that's the point. I don't really know why I do open source hardware, I don't even have to know what it is. But somehow, it feels good to make and produce open electronics, open source code examples that control those electronics, and devices that are in general far more accessible and hackable than previous generations of hardware.
So I'll keep doing "open source hardware" even though I have no idea what it means, whether the term carries any substance, because... it just feels right!
Of course, there were so many more thoughts running through my mind than I could possibly share with the group, and I didn't want to monopolize the speaking time, so I took lots of notes. Here are a few of the notes I jotted down:
-What is the relationship between open source rights and intellectual property protection provided by the government?
-Is an open source design patentable? Is it copyrightable? Is it trademarkable?
-Open source hardware designs are getting licensed to hardware builders for rates around 5-10%, yet patented technologies have concepts like compulsory rates of 3%. Does that mean that patented designs might actually be cheaper than open source?
-Does an open source design have to be recursive and/or fractal? Can you have an open source design that uses proprietary integrated circuit chips? Can you use an open source circuit in a proprietary, closed device?
-Many of the successful open source hardware projects have in common that they rigorously protect one aspect of their business: arduino gives away the board but keeps the brand and trademark, beagleboard gives away the design by keeps the chip gate array design, bug labs gives away the schematics but restricts the inter-module snap-connect interface, liquidware gives away the hardware at cost, but keeps the analytical algorithms (e.g. you can buy a "military grade" IXM, but you can't get the code that turns it into a --CLASSIFIED--) Exactly :-)
-What do you use to base an open source hardware license on? Does it start from a contract that restricts freedom to operate, and use, or does it look more like wills and testament document, where it gives away rights and freedoms?
-Is the goal of open source to provide freedoms? If so, why does it need a license or contract to restrict rights?
-What is the relationship between the drivers and motivators of hackers, and the objective of a license? Could you have had open source software without the GNU?
-What came first: the license, or open source code?
-What is the "source" part of open source hardware? Does hardware have a standard "source" (no)? How long will it take to get there (a long time)?
All in all, I think - as always - I'm left with many more questions than answers, but I think that's the point. I don't really know why I do open source hardware, I don't even have to know what it is. But somehow, it feels good to make and produce open electronics, open source code examples that control those electronics, and devices that are in general far more accessible and hackable than previous generations of hardware.
So I'll keep doing "open source hardware" even though I have no idea what it means, whether the term carries any substance, because... it just feels right!
Labels:
Liquidware
Tuesday, September 21, 2010
How to build a BeagleBoard-based Open Source Ebook Reader
Ebook readers were hailed several months ago as the end-all-be-all of digital devices. They were supposed to put books out of business. In effect they have, they've put some book distributors out of business. But somehow, the Ebook itself is somewhat unsatisfying - after all the hoopla, we're left with "just" a screen tablet-like device, with a few buttons and a mini keyboard. It just doesn't feel like there's enough new to it... so I got inspired to build my own as a platform for experimenting with the "user experience" of Ebooks.
I got bored with my Kindle after about 20 times using it, and started wanting to hack it. I have a modern form of A.D.D. that makes me want to break open cases and solder memory expansion ports onto any device I touch. There's so much I'd do differently, yet you can't really do any development on it - I don't understand - they should just open it up, and let people like me hack away at it.
Since Amazon didn't, and doesn't, I decided to turn the Open SciCal into a hackable ebook reader, based on the FBReader source code. This means that it's hackable from the ground up...
It's not bad, but there are some things I'd change. Luckily I can, because the source is open and accessible... in fact, it's quite easy to understand - here's the important main function set, from FBReader, which gives a good idea of how approachable the code is (if you know C and C++, that is):
void FBReader::openBookInternal(shared_ptr book) {
if (!book.isNull()) {
BookTextView &bookTextView = (BookTextView&)*myBookTextView;
ContentsView &contentsView = (ContentsView&)*myContentsView;
FootnoteView &footnoteView = (FootnoteView&)*myFootnoteView;
bookTextView.saveState();
bookTextView.setModel(0, 0);
bookTextView.setContentsModel(0);
contentsView.setModel(0);
myModel.reset();
myModel = new BookModel(book);
ZLTextHyphenator::Instance().load(book->language());
bookTextView.setModel(myModel->bookTextModel(), book);
bookTextView.setCaption(book->title());
bookTextView.setContentsModel(myModel->contentsModel());
footnoteView.setModel(0);
footnoteView.setCaption(book->title());
contentsView.setModel(myModel->contentsModel());
contentsView.setCaption(book->title());
Library::Instance().addBook(book);
Library::Instance().addBookToRecentList(book);
((RecentBooksPopupData&)*myRecentBooksPopupData).updateId();
showBookTextView();
}
}
The Open Source Ebook reader is based on a handful of modules:
-BeagleBoard - the guts of my Ebook uses the TI OMAP
-BeagleTouch - it has a touchscreen OLED screen
-BeagleJuice - it's powered for 8 hours at a time with lithium ions
-FBReader - open source software, quite nice and hackable
-Liquidware Ebook Boot - an open source boot SD card with a tweaked version of Angstrom to integrate all the parts
The base parts are pretty straight-forward, they just snap together and go. If you're a hacker, you could build it all together pretty straightforward-like from source and use Angstrom. But if you're lazy, you can just buy the "Ebook Boot" SD card which took Chris and Will and me about 2 weeks of hacking around to build, from source, from scratch. It includes all of the drivers needed to get the touchscreen working within Linux, and a handful of libraries and scripts to make wifi, power management, screen control, etc. work right out of the box...
The fully combined stack of modules makes an Ebook:
Here it is from another angle, against a go table that I built by hand (those lines took forever, and were done with a heat iron, for wood carving, but it was so worth it):
This photo is probably the most "ironic" given it's a shot perhaps the most purpose-built hackable Ebook reader on top of the perhaps the most purpose-built non-hackable devices ever: a Mac laptop.
This is probably my favorite picture:
I haven't tried it yet, but conceivably, it could be connected to the net using the Wifi module, and then it could download Ebooks and free Ebooks from the various online stores that FBReader lets you connect to...
I've uploaded some pictures over on the flickr page, and the modules and finished EbookBoot SD Card are all available over at the Liquidware shop... I think I should run a timed contest against myself on how many different types of gadgets I can build within 4 minutes, like these guys that Make blog featured a little while ago...
:-)
I got bored with my Kindle after about 20 times using it, and started wanting to hack it. I have a modern form of A.D.D. that makes me want to break open cases and solder memory expansion ports onto any device I touch. There's so much I'd do differently, yet you can't really do any development on it - I don't understand - they should just open it up, and let people like me hack away at it.
Since Amazon didn't, and doesn't, I decided to turn the Open SciCal into a hackable ebook reader, based on the FBReader source code. This means that it's hackable from the ground up...
It's not bad, but there are some things I'd change. Luckily I can, because the source is open and accessible... in fact, it's quite easy to understand - here's the important main function set, from FBReader, which gives a good idea of how approachable the code is (if you know C and C++, that is):
void FBReader::openBookInternal(shared_ptr
if (!book.isNull()) {
BookTextView &bookTextView = (BookTextView&)*myBookTextView;
ContentsView &contentsView = (ContentsView&)*myContentsView;
FootnoteView &footnoteView = (FootnoteView&)*myFootnoteView;
bookTextView.saveState();
bookTextView.setModel(0, 0);
bookTextView.setContentsModel(0);
contentsView.setModel(0);
myModel.reset();
myModel = new BookModel(book);
ZLTextHyphenator::Instance().load(book->language());
bookTextView.setModel(myModel->bookTextModel(), book);
bookTextView.setCaption(book->title());
bookTextView.setContentsModel(myModel->contentsModel());
footnoteView.setModel(0);
footnoteView.setCaption(book->title());
contentsView.setModel(myModel->contentsModel());
contentsView.setCaption(book->title());
Library::Instance().addBook(book);
Library::Instance().addBookToRecentList(book);
((RecentBooksPopupData&)*myRecentBooksPopupData).updateId();
showBookTextView();
}
}
The Open Source Ebook reader is based on a handful of modules:
-BeagleBoard - the guts of my Ebook uses the TI OMAP
-BeagleTouch - it has a touchscreen OLED screen
-BeagleJuice - it's powered for 8 hours at a time with lithium ions
-FBReader - open source software, quite nice and hackable
-Liquidware Ebook Boot - an open source boot SD card with a tweaked version of Angstrom to integrate all the parts
The base parts are pretty straight-forward, they just snap together and go. If you're a hacker, you could build it all together pretty straightforward-like from source and use Angstrom. But if you're lazy, you can just buy the "Ebook Boot" SD card which took Chris and Will and me about 2 weeks of hacking around to build, from source, from scratch. It includes all of the drivers needed to get the touchscreen working within Linux, and a handful of libraries and scripts to make wifi, power management, screen control, etc. work right out of the box...
The fully combined stack of modules makes an Ebook:
Here it is from another angle, against a go table that I built by hand (those lines took forever, and were done with a heat iron, for wood carving, but it was so worth it):
This photo is probably the most "ironic" given it's a shot perhaps the most purpose-built hackable Ebook reader on top of the perhaps the most purpose-built non-hackable devices ever: a Mac laptop.
This is probably my favorite picture:
I haven't tried it yet, but conceivably, it could be connected to the net using the Wifi module, and then it could download Ebooks and free Ebooks from the various online stores that FBReader lets you connect to...
I've uploaded some pictures over on the flickr page, and the modules and finished EbookBoot SD Card are all available over at the Liquidware shop... I think I should run a timed contest against myself on how many different types of gadgets I can build within 4 minutes, like these guys that Make blog featured a little while ago...
:-)
Labels:
Liquidware
Monday, September 20, 2010
I'm heading to Maker Faire NY!
This week is Maker Faire New York City, and it holds a special place in my heart, for a number of reasons. A large part is because Maker Faire is where I started out, 3 years ago, with my humble little TouchShield Legacy and Arduino. At the time, I was traveling quite a bit for my day job, and barely had time to sit in one place long enough to do any serious development.

Maker Faire
New York
September 25, 26 2010
Fast forward to the present - now I live in Boston, and after three years of driving or flying myself out to San Mateo for Maker Faire's, I'm pretty excited to have one in my own back yard... relatively speaking, that is.
In the past, I've set up tables with some of my favorite hacks. But this time, I'm going to be joined by Justin, Will, and Francis, fellow hackers at Liquidware. And instead of showing off only just my Open Source Hardware hacks, all 4 of us are going to bring along demos and hacks using the latest gadgets.
And at least one of the projects hasn't really been blogged about, because it's still in demo form. Dun dun dun :-)
Ok, back to packing for a busy week ahead...

Maker Faire
New York
September 25, 26 2010
Fast forward to the present - now I live in Boston, and after three years of driving or flying myself out to San Mateo for Maker Faire's, I'm pretty excited to have one in my own back yard... relatively speaking, that is.
In the past, I've set up tables with some of my favorite hacks. But this time, I'm going to be joined by Justin, Will, and Francis, fellow hackers at Liquidware. And instead of showing off only just my Open Source Hardware hacks, all 4 of us are going to bring along demos and hacks using the latest gadgets.
And at least one of the projects hasn't really been blogged about, because it's still in demo form. Dun dun dun :-)
Ok, back to packing for a busy week ahead...
Labels:
Liquidware
Book burning post mortem: digital destruction
Lately I've been reading Joseph Schumpeter's writings on Creative Destruction, in preparation for the upcoming Open Hardware Summit this coming week. I know, some heavy stuff... So my head has been thinking about destruction and acts of purposeful damage.
I've gotten a handful of funny emails and comments in conversations over the past few days in response to my article about book burning, so I thought I'd give it a quick summary of my favorite additional ideas. Far be it from me to beat a dead joke any further than it needs to go (not really, I do it all the time), but I do think there's something worth contemplating here, about the future of book burning.
The essence is: digital desecration is far more nuanced than book burning. You simply have more options to be obnoxious.
In no particular order:
Probably not.
I've gotten a handful of funny emails and comments in conversations over the past few days in response to my article about book burning, so I thought I'd give it a quick summary of my favorite additional ideas. Far be it from me to beat a dead joke any further than it needs to go (not really, I do it all the time), but I do think there's something worth contemplating here, about the future of book burning.
The essence is: digital desecration is far more nuanced than book burning. You simply have more options to be obnoxious.
In no particular order:
- Burning isn't good enough, you also have to explicitly destroy some of the content
- There is a close relationship between desecration and information defacing
- Digital desecration opens up a more complex relationship between destruction of the physical object, the file, the creative medium, the idea, and the ideology
- In the digital desecration world, each of these are explicitly different stages (in that sense, is book burning in the traditional sense more effective? will we one day pine for the good ol' days when book burning was as easy as applying incendiaries to paper?)
- A corollary is that the more creative effort that went into a work of art, the more "satisfying" it is to desecrate (e.g. destroying that which took seconds to build is somewhat lame)
- A further corollary suggests the ratio of time invested in desecration should somehow be far less than the time someone else invested in the act of creating
- At the ASCII level, digital defacing might include something like taking a concept or idea, and overwriting or padding it with the word "sucks"
- At the byte level, you could swap the Endianness of the double chars in order to make it unreadable by whatever chip it's on
- At the binary level, you could AND or XOR the binary with a random binary sequence, in order to truly make it obfuscated and irretrievable (thanks Devlin)
- At the file level, you could overwrite pieces of text with strategically identified counter-points or antithetical topics
- At the archive level, you might rename the cover or title of the file to something misleading, in order to deceive the next potential reader
- At the chip level, you could create a mechanism that actually made the chip on which bytes were stored burst into flames, moving into the real physical world for some tangible destruction (thanks Chris)
- At the web level, you could Google bomb the concept or title of the Ebook or text, so that when it's Googled, other links come up at the top that are actually propaganda for something else
- You could try to measure the performance of desecration by converting electron energy into mass using E=mc^2
- Less heat is generated from digital desecrations, implying less "wasted energy", and instead there is a more efficient thermodynamic transformation, directing more energy at desecration than being lost as radiating heat
Probably not.
Labels:
Liquidware
Thursday, September 16, 2010
Book-burning needs to modernize
To make things perfectly clear: I do not recommend emotional book burning. I think it's wrong and inefficient. I'm simply going to say this: If you're going to do "book burning" I believe you need to find a more modern way to achieve your goals. Use technology. Better yet, use Open Source technology to achieve your goals.
Something about the press release events of the past week or so has rubbed me the wrong way. But not because of the reasons already expressed by the "media". It's because the guy in Florida is doing it all wrong. We live in a world with headlines filled with stories about Barnes and Noble and Borders books going bankrupt or being sold. Ebooks are taking over. Who can afford to think about burning books at a time like this?
In order to have a serious book burning, there's a serious time investment. You'd first have to find the book you wanted to burn, order copies from 10 different retailers on Amazon, pick the most worthy copy, and then commence burning. You'd probably use some social media site to send out Evites or set up a Facebook event hoping people would pull themselves away from Farmville long enough to sit around watching a book burn. What a pain in the rear. If I think about some of my friends, I highly doubt that a book burning event would even hold their attention for more 30 seconds before they were checking their iPhones and Android phones, or sending email on their Blackberries.
When is book burning ok?
If I were homeless in the winter, in a cold climate, and had no other source of shelter, but had plenty of books and matches, I would hope people wouldn't judge me if I were to burn the books I had collected. Alternatively, if I were filming a movie about World War II, or a documentary about a time when books were burned, for historical accuracy, I hope people would appreciate that as art. I suppose if I were the author of the books, it's ok to burn them.
This last reason is cause for serious suspicion. It supposes that there is a relationship between the intellectual property and creative process of writing, authorship, and acceptability of burning books.
What happens when you burn books (or blogs)?
Books are actually not so easy to find that I would actually be willing to burn, so I'm burning something closer to my heart. But first, this is me burning a set of blank pieces of paper:
No emotion. Some heat felt. Fire consumed 3 sheets of paper within 62 seconds, for a rate of 2.90 pages / minute.
It wasn't easy finding books I was willing to burn, mostly because I like to take notes in the margins, which I find useful. So instead, this is me burning a recent article from the Antipasto Hardware Blog:
EMOTION!!! Some heat felt. Fire consumed 4 pages within 1:48 at a rate of 2.22 pages / minute. The pages were printed with 1622 words across 189 lines, or 7750 characters.
Another way to say this is, my book burning experiment consumed 143.5 bytes / second.
I'm going to assume that the way I folded the paper to allow oxygen in had more to do with the rate of burn than factors like wind (there wasn't any), flammability or not of the ink, or perhaps because my writing is so bad, it burns faster because thermodynamic principles are trying to undo the entropy I create.
What's the difference?
Thought Experiment: Why do people burn books?
I believe that books are burned for several reasons, not limited to the following list:
-Heat
-Light
-Waste disposal
-Publicity leading to social unity
-Desecration
I'll address each one in turn:
-Heat. Not great support for burning books. Modern heaters are known to be more efficient. Plus burning books isn't the quickest, easiest way to generate heat.
-Light. Also not great support for burning books. LED lights are a much more efficient way to achieve this.
-Waste. So so. Just throw it in a landfill, or plant it at the base of a tree to fertilize it. Burning many books, however, may save the time and energy to lug them all to a landfill, so it's a toss-up here for me.
-Publicity leading to social unity. Probably a toss up. This is a lot of effort, and you likely have to create significant consternation before you'll get noticed in the mainstream press.
-Desecration. Now this, I think, is the important point.
Measuring Book Burning Performance: Desecrations / Second
Steve Jobs would probably burn the second volume of my book. Because it's all about Open Source Hardware Strategy and Economics, like what Google uses. Steve hates Open Source, Google, and things that are Open Source like Android, so it's understandable that he might seek to desecrate ideas associated with them.
But here's the problem: if you're going for desecrations, why settle for mediocrity? Why not go all out and desecrate in a modern, digital way?
Here's some Arduino code I wrote to do desecrations:
Running this sketch achieves 30,000 digital desecrations within roughly 800 milliseconds. This is an effective desecration rate of 1,440,000 desecration-bytes / second!
This Arduino should be ashamed of itself:
It instantiates an array with a phrase, filled with digital bytes of information, and then deletes it from memory. But it does so in the most desecratory way you could imagine: 1 helpless, bloody char at a time - and not even with civil memory management!? From a programmer's point of view, this is heresay. This is like torturing a person by pulling his fingernails out one by one, like every one of those Saw movies. It's like tearing out the pages of a book one by one, and then burning it. Couldn't you have just dereferenced the array pointer, and left the char array in memory? Or if you have to move on, why not just call memory purge?
Ladder of desecration:
Bad: Buying book and burning it (plain form desecration 101)
Worse: Stealing book and burning it (not participating in the economic incentivization system)
Worst: Stealing book, ripping pages out, then burning (physical acts included)
Likewise, here's the digital ladder of desecration:
Bad: Removing software or deleting an ebook from your device
Worse: Torrenting the software and Ebook, and then deleting it
Worst: Torrenting the software and Ebook, and then deleting it, one character or word at a time
Here's some plain R-code to do the same task:
R
x=readLines("OSHWBook.txt");
x <- NULL;
Eh, not a huge impact on my emotions. But this is a completely different story:
R
x=readLines("OSHWBook.txt");
for(j in 1:length(x)) {
for(i in 1:nchar(x[j])) {
x[j][i]="";
}}
x <- NULL;
Seriously?!?!! Is that middle step really necessary? If you're going to delete something just throw it out. There's no need to iteratively replace bytes in memory - without even a simple purge. That's unnecessary and ridiculous.
To me, book burning just doesn't have the same impact as it did when the scholars looked on as the Library of Alexandria was burned to the ground. But this R code hurts. And it's going above and beyond the call to destroy.
Benchmarking Digital Desecration Performance
One could argue that you could measure the strict word count (which is like page count). You could measure file size in bytes, but that's a proxy for document length. You could measure unique words. You could even measure Shannon complexity of the document.
I think there's an open question, perhaps requiring further research, to examine whether or not it makes sense to count bytes, characters, words, or perhaps on synonyms of a specific trigger word or phrase that is considered "desecratory". Perhaps there is an ontological argument to be made about the distribution of desecratory-capable phrases in a document (does it follow a long tail?).
I would argue you want to measure the entropy of the desecrations, which I will define as: number of RAM instantiations and removals of bytes associated with the topic to be desecrated.
Generalization
So I have established a relationship, which I will put in the 2x2 matrix below:
Implementation
Here's some Arduino code that runs on the Arduino and blinks a red LED every time a desecration takes place.
void setup() {
pinMode(13, OUTPUT);
Serial.begin(9600);
}
void loop() {
Serial.println("Start");
Serial.println(millis());
for (int j=0;j<=30000;j++){
char a[] = "Open Source Hardware is the future.";
for(int i=0;i<=strlen(a);i++){
a[i]=0;
}
}
Serial.println(millis());
Serial.println("Done desecrating 30,000 times.");
digitalWrite(13, HIGH); delay(1000);
digitalWrite(13, LOW); delay(1000);
}
Here's the Open SciCal running desecration.r desecrations script:
x=readLines("OSHWBook.txt");
for(j in 1:length(x)) {
for(i in 1:nchar(x[j])) {
x[j][i]="";
}}
x <- NULL;
Conclusion
I believe book burning is about the public destruction of intellectual property. In a world over-run with new forms of media, and open source software and hardware, however, we need to catch up with the times. I applaud people for having strong beliefs, but if you're going to desecrate someone's intellectual property or creative works, then do so with a modern toolkit!
And do it with Open Source Hardware, why don't you, so others can share in your destructive acts!
:-)
Something about the press release events of the past week or so has rubbed me the wrong way. But not because of the reasons already expressed by the "media". It's because the guy in Florida is doing it all wrong. We live in a world with headlines filled with stories about Barnes and Noble and Borders books going bankrupt or being sold. Ebooks are taking over. Who can afford to think about burning books at a time like this?
In order to have a serious book burning, there's a serious time investment. You'd first have to find the book you wanted to burn, order copies from 10 different retailers on Amazon, pick the most worthy copy, and then commence burning. You'd probably use some social media site to send out Evites or set up a Facebook event hoping people would pull themselves away from Farmville long enough to sit around watching a book burn. What a pain in the rear. If I think about some of my friends, I highly doubt that a book burning event would even hold their attention for more 30 seconds before they were checking their iPhones and Android phones, or sending email on their Blackberries.
When is book burning ok?
If I were homeless in the winter, in a cold climate, and had no other source of shelter, but had plenty of books and matches, I would hope people wouldn't judge me if I were to burn the books I had collected. Alternatively, if I were filming a movie about World War II, or a documentary about a time when books were burned, for historical accuracy, I hope people would appreciate that as art. I suppose if I were the author of the books, it's ok to burn them.
This last reason is cause for serious suspicion. It supposes that there is a relationship between the intellectual property and creative process of writing, authorship, and acceptability of burning books.
What happens when you burn books (or blogs)?
Books are actually not so easy to find that I would actually be willing to burn, so I'm burning something closer to my heart. But first, this is me burning a set of blank pieces of paper:
No emotion. Some heat felt. Fire consumed 3 sheets of paper within 62 seconds, for a rate of 2.90 pages / minute.
It wasn't easy finding books I was willing to burn, mostly because I like to take notes in the margins, which I find useful. So instead, this is me burning a recent article from the Antipasto Hardware Blog:
EMOTION!!! Some heat felt. Fire consumed 4 pages within 1:48 at a rate of 2.22 pages / minute. The pages were printed with 1622 words across 189 lines, or 7750 characters.
Another way to say this is, my book burning experiment consumed 143.5 bytes / second.
I'm going to assume that the way I folded the paper to allow oxygen in had more to do with the rate of burn than factors like wind (there wasn't any), flammability or not of the ink, or perhaps because my writing is so bad, it burns faster because thermodynamic principles are trying to undo the entropy I create.
What's the difference?
Thought Experiment: Why do people burn books?
I believe that books are burned for several reasons, not limited to the following list:
-Heat
-Light
-Waste disposal
-Publicity leading to social unity
-Desecration
I'll address each one in turn:
-Heat. Not great support for burning books. Modern heaters are known to be more efficient. Plus burning books isn't the quickest, easiest way to generate heat.
-Light. Also not great support for burning books. LED lights are a much more efficient way to achieve this.
-Waste. So so. Just throw it in a landfill, or plant it at the base of a tree to fertilize it. Burning many books, however, may save the time and energy to lug them all to a landfill, so it's a toss-up here for me.
-Publicity leading to social unity. Probably a toss up. This is a lot of effort, and you likely have to create significant consternation before you'll get noticed in the mainstream press.
-Desecration. Now this, I think, is the important point.
Measuring Book Burning Performance: Desecrations / Second
Steve Jobs would probably burn the second volume of my book. Because it's all about Open Source Hardware Strategy and Economics, like what Google uses. Steve hates Open Source, Google, and things that are Open Source like Android, so it's understandable that he might seek to desecrate ideas associated with them.
But here's the problem: if you're going for desecrations, why settle for mediocrity? Why not go all out and desecrate in a modern, digital way?
Here's some Arduino code I wrote to do desecrations:
void setup() {
pinMode(13, OUTPUT);
Serial.begin(9600);
}
void loop() {
Serial.println("Start");
Serial.println(millis());
for (int j=0;j<=30000;j++){
char a[] = "Open Source Hardware is the future.";
for(int i=0;i<=strlen(a);i++){
a[i]=0;
}
}
Serial.println(millis());
Serial.println("Done desecrating 30,000 times.");
digitalWrite(13, HIGH); delay(1000);
digitalWrite(13, LOW); delay(1000);
}
Running this sketch achieves 30,000 digital desecrations within roughly 800 milliseconds. This is an effective desecration rate of 1,440,000 desecration-bytes / second!
This Arduino should be ashamed of itself:
It instantiates an array with a phrase, filled with digital bytes of information, and then deletes it from memory. But it does so in the most desecratory way you could imagine: 1 helpless, bloody char at a time - and not even with civil memory management!? From a programmer's point of view, this is heresay. This is like torturing a person by pulling his fingernails out one by one, like every one of those Saw movies. It's like tearing out the pages of a book one by one, and then burning it. Couldn't you have just dereferenced the array pointer, and left the char array in memory? Or if you have to move on, why not just call memory purge?
Ladder of desecration:
Bad: Buying book and burning it (plain form desecration 101)
Worse: Stealing book and burning it (not participating in the economic incentivization system)
Worst: Stealing book, ripping pages out, then burning (physical acts included)
Likewise, here's the digital ladder of desecration:
Bad: Removing software or deleting an ebook from your device
Worse: Torrenting the software and Ebook, and then deleting it
Worst: Torrenting the software and Ebook, and then deleting it, one character or word at a time
Here's some plain R-code to do the same task:
R
x=readLines("OSHWBook.txt");
x <- NULL;
Eh, not a huge impact on my emotions. But this is a completely different story:
R
x=readLines("OSHWBook.txt");
for(j in 1:length(x)) {
for(i in 1:nchar(x[j])) {
x[j][i]="";
}}
x <- NULL;
Seriously?!?!! Is that middle step really necessary? If you're going to delete something just throw it out. There's no need to iteratively replace bytes in memory - without even a simple purge. That's unnecessary and ridiculous.
To me, book burning just doesn't have the same impact as it did when the scholars looked on as the Library of Alexandria was burned to the ground. But this R code hurts. And it's going above and beyond the call to destroy.
Benchmarking Digital Desecration Performance
One could argue that you could measure the strict word count (which is like page count). You could measure file size in bytes, but that's a proxy for document length. You could measure unique words. You could even measure Shannon complexity of the document.
I think there's an open question, perhaps requiring further research, to examine whether or not it makes sense to count bytes, characters, words, or perhaps on synonyms of a specific trigger word or phrase that is considered "desecratory". Perhaps there is an ontological argument to be made about the distribution of desecratory-capable phrases in a document (does it follow a long tail?).
I would argue you want to measure the entropy of the desecrations, which I will define as: number of RAM instantiations and removals of bytes associated with the topic to be desecrated.
Generalization
So I have established a relationship, which I will put in the 2x2 matrix below:
Implementation
Here's some Arduino code that runs on the Arduino and blinks a red LED every time a desecration takes place.
void setup() {
pinMode(13, OUTPUT);
Serial.begin(9600);
}
void loop() {
Serial.println("Start");
Serial.println(millis());
for (int j=0;j<=30000;j++){
char a[] = "Open Source Hardware is the future.";
for(int i=0;i<=strlen(a);i++){
a[i]=0;
}
}
Serial.println(millis());
Serial.println("Done desecrating 30,000 times.");
digitalWrite(13, HIGH); delay(1000);
digitalWrite(13, LOW); delay(1000);
}
Here's the Open SciCal running desecration.r desecrations script:
x=readLines("OSHWBook.txt");
for(j in 1:length(x)) {
for(i in 1:nchar(x[j])) {
x[j][i]="";
}}
x <- NULL;
Conclusion
I believe book burning is about the public destruction of intellectual property. In a world over-run with new forms of media, and open source software and hardware, however, we need to catch up with the times. I applaud people for having strong beliefs, but if you're going to desecrate someone's intellectual property or creative works, then do so with a modern toolkit!
And do it with Open Source Hardware, why don't you, so others can share in your destructive acts!
:-)
Labels:
Liquidware
Wednesday, September 15, 2010
Learning PWM with Illuminato Genesis and TouchShield Slide
With the relaunch of the Illuminato Genesis (which was featured on Make Blog a while back), I figured I'd whip together an app that showed off the what the Illuminato Genesis can do. I've been spending a lot of time with the BeagleBoard recently, and that's clearly a top end type device, but the Arduino and Illuminato Genesis plus TouchShield Slide make a nice gadget at the lower end of the spectrum, especially for smaller handheld apps.
I've wrapped everything up into an app on the Open Source App Store over here. The app includes 3 files:
So the first step was to implement PWM light control, which is accomplished with this snippet of code:
Then, using serial communications between the Illuminato Genesis and the TouchShield Slide, the PWM'ing is synchronized so that both boards are pulsing at the same speed. The effect is pretty cool looking, if you ask me. On the one hand, you have real LED's on the back of the Illuminato pulsing, and then you have virtual LED's on the TouchShield Slide's OLED pulsing.
Here's the video:
And here are some other pictures:
I've wrapped everything up into an app on the Open Source App Store over here. The app includes 3 files:
- SoftwareSerial_NB.zip - This should be dropped into folder: hardware\arduino\cores\genesis\src\components\library
- TouchShield_Pulsing_Sleep.pde - This is a sketch that implements the PWM duty cycle value to the Illuminato Genesis, using the bling() function
- Illuminato_Serial_Bling.pde - Listens for PWM duty cycle value from the TouchShield and controls the virtual bling LEDs on the front of the TouchShield Slide
So the first step was to implement PWM light control, which is accomplished with this snippet of code:
/* Software PWM modulation routine */
void pwm_bling(char duty) {
int duration;
duration = (millis() - pTime);
if (duration <= duty) {
bling(1);
} else {
bling(0);
}
if (duration >= period ) {
pTime = millis();
}
}
Then, using serial communications between the Illuminato Genesis and the TouchShield Slide, the PWM'ing is synchronized so that both boards are pulsing at the same speed. The effect is pretty cool looking, if you ask me. On the one hand, you have real LED's on the back of the Illuminato pulsing, and then you have virtual LED's on the TouchShield Slide's OLED pulsing.
Here's the video:
And here are some other pictures:
Labels:
Liquidware
Tuesday, September 7, 2010
How to make a BeagleBoard Elastic R Beowulf Cluster in a Briefcase
The BeagleBoard's OMAP chip has some serious computing chops, and this project set out to prove it. Ever since I built the Open SciCal, I've been showing it off to nerd friends of mine (that's another way of saying, if I've showed your the Open SciCal in the past 2 weeks, I think you're a nerd that would appreciate it - ha). Granted, a single Open SciCal is nice. But the real impressive part is the combination of serious floating point horsepower with low power.
I figured I'd do this project to respond to all those people who were skeptical that the Open SciCal had any utility in the modern world. Well... my answer is yes.
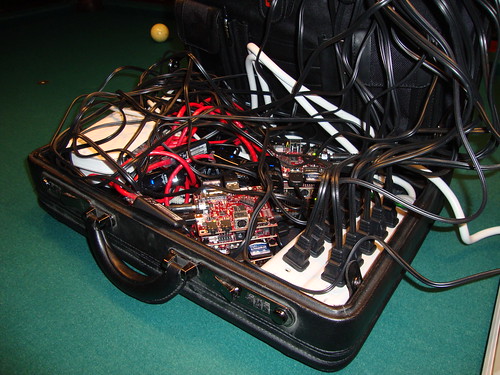
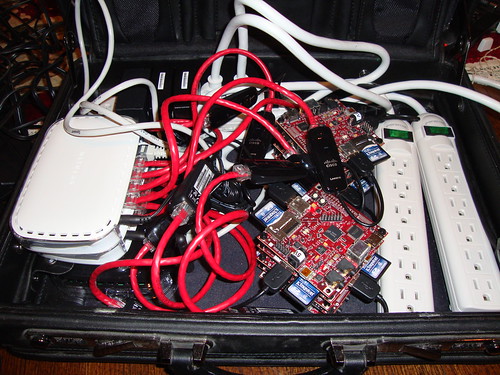
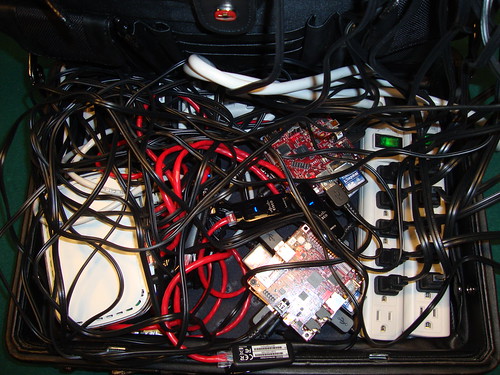
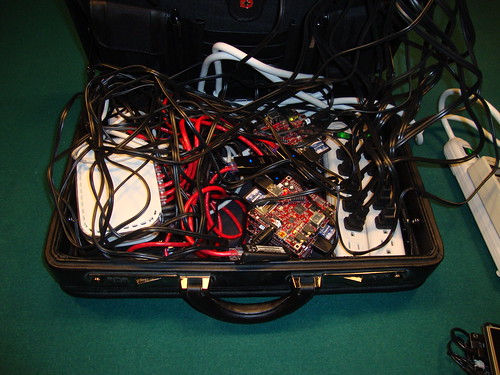
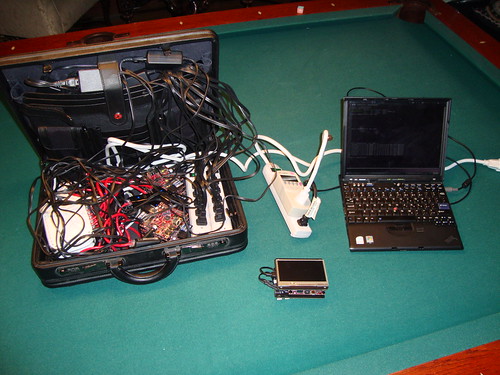
I took 10 BeagleBoards and turned a suitcase into a wifi-accessible, on-demand, elastic R computer cluster that runs at 10 Ghz, 40 Gigs of disk, and 1,000 megabits of networking bandwidth. I did this all for less than $2,000, and spent less than 5 hours building it, and now I have a scalable compute resource that is portable, has performance comparable to mid-range and high end servers that cost $15,000-30,000 from IBM or Sun. And better yet, it all runs at 30 Watts. That's less than most of the incandescent light bulbs in my room right now.
I've also made the whole project Open Source, for anyone who wants to replicate it on their own. Personally, I'm going to build another one out of 32 of these suckers, and rent it to the trading firm that bought dozens of Open SciCal's from me in the past couple weeks.
Step 1: Get 10 BeagleBoards
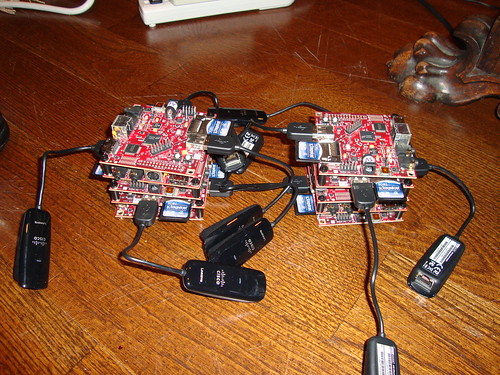
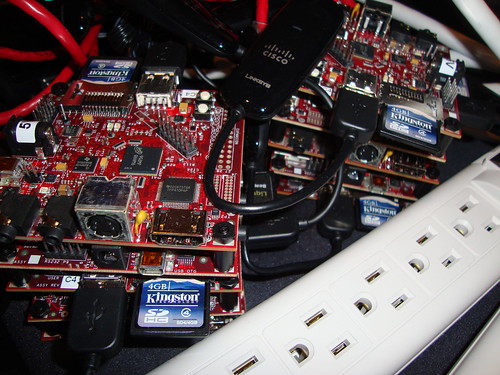
I took 10 BeagleBoards, and used the same standoffs that I use in the Embedded Gadget Pack. I used an offset pattern so they could stack as high as I wanted them to. I built them all the way up to 10, and then decided it wouldn't fit in a suitcase, so I split them up into 2 mini-towers of 5 BeagleBoards each.
Step 2: Buy 3 cheap, low power hubs
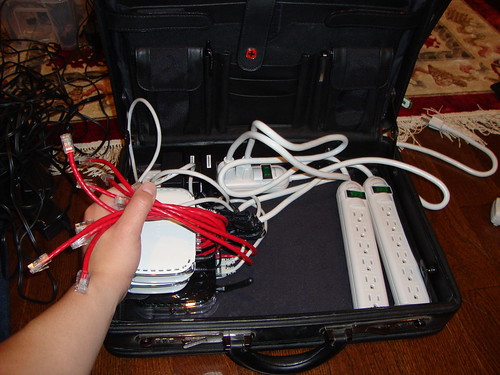
I went to Radio Shack (begrudgingly because they sold out to the cell phone man in 2000 and have sucked ever since), since they were the only ones open. I bought 1 wireless router with 5 ethernet ports in the back, and then bought 2 netgear hubs (each had 5 ethernet ports).
Step 3: Wire the "interconnection backplane"
I've been reading old literature about multicore, multi-processor, scalable computer architectures, and they have a funky way of making simple concepts like "network" sound really complex like "Fat Tree Fishbone N-Way Scalable Interconnection Backplane".
Oh so you mean I plugged the two hubs into the wireless router, and then put 4 wires into each of the hubs, and 2 from the router, and connected them to the BeagleBoards with USB-to-Ethernet modules.
Like this:
I have this new mantra that things I read in hefty academic papers are written in language way too fancy for what they're trying to do. I get the sense that this is intentional, to hide the fact that what they researched could be replicated for $2,000 and 5 hours in modern times. I kid, partially. I'm reading papers written in the 1980's and 1990's, when the idea of doing what I just did would have taken a $10,000,000 DARPA grant.
Step 4: Set up the Open SciCal Slave Nodes
Each of the BeagleBoards is running the Open SciCal SD card from Liquidware, with a few notable additions:
-Each card is configured to allow passwordless logins over dropbear SSH
-Each card auto-configures itself to a static IP address
-The cards have a slightly trimmed down set of background apps to make R more responsive
I then replicated the card 10 times, onto each of my SD cards.
Step 5: Build the Power Backbone
This was an easy step conceptually, but a pain to do in an organized manner. So I gave up the organization, and just hacked through it. I took 10 BeagleBoard power connectors from the Liquidware shop (specifically those because they're low wattage). And connected them into two small outlet strips.
I then routed those power cables around and through to each of the 10 Open SciCal BeagleBoard Compute Nodes.
For kicks, I got one of those "kill-a-watt" meters and put it in front of the whole set up, so I could measure how much power the whole thing consumed.
Step 6: Configure the Master
Parallel architecture guys are always labeling nodes "master" and "slave". I think it's some hidden repressed anger at the fact that most of us "nerds" never got picked first for kick-ball and 4-square (the game, not the GPS website) when we were kids. Take that, 2nd grade. Now look who's deciding who's "master" and "slave". Me.
In all seriousness, at this point in the project, I had 10 networked Open SciCal nodes. But no way to issue code to them. So I took out my trusty Ubuntu Linux laptop, and quickly got it to connect to the wireless G router I'd set up to be the master switch for all 10 of the BeagleBoards.
Since the system is running on R, I naturally tried to get some of their default environments running, like Snow, Snowfall, svSockets, and even MPI. But each of those turned out to be serious overkill. Sure, they're easy to use if someone else is installing them for you and you don't have to think about it, but they didn't really get the job done in the amount of time I was willing to dedicate, so I wrote my own scripts.
Here are all of the programs I wrote, in one "app" on the "Open Source App Store".
Step 7: Write Elastic R Programs
I was hired by a company a couple months ago to write data mining algorithms to run on the Open SciCal. Most of them were top secret, but a few were pretty elementary. For instance, one function that is used often in text data mining is a function to extract all capitalized phrases. For instance, Amazon uses this on their website to summarize books with a few phrases.
Here's the R code that extracts the indexed location of any capitalized word in a piece of text:
This is a piece of code that you'd often want to run against 1,000's of pieces of text at a time, to extract important pieces of information. I wrote this into a program called "upper.r".
I then wrote some "administrative" functions for my homemade Elastic R Beowulf cluster - you can download them here:
"esh" - "elastic shell" - this runs a command on all of the slave nodes, and kicks back the output
For instance: esh "uname -a"
"ecp" - "elastic copy" - this copies a file to the home/root/ directory of each of the slave nodes
"epush" - "elastic data replicate push" - this takes a set of data files in the data/ folder called "1.txt" "2.txt" "3.txt" etc. all the way up to "10.txt" and copies them over to each node as /home/root/data.txt. This is important if you want to parallelize different data across to each of the nodes.
"epull" - "elastic data extract pull" - this does the inverse of "epush" in that it pulls a single file called /home/root/out.txt off each of the nodes, and renames them locally into the "out/" folder as "1.txt" "2.txt" "3.txt" etc. according to which node it came off
A typical session would look something like this:
esh "uname -a"
ecp upper.r
epush data.txt
esh "R BATCH < href="http://en.wikipedia.org/wiki/MapReduce">Map/Reduce". If you wrote about parallel computing in the 1980's, you would call it "Distribute/Evaluate/Collect". If you worked at Wolfram Media, you'd call it "ParallelDistribute/ParallelMap". Or if you hacked on the Cray, you'd call it "LoadVec/ParVec/PopVec". At NVIDIA you'd probably call this "CUDALoad/CUDAExecute". Or if you were the CEO of Amazon, I supposed you'd call it "Elastic Cloud Map Reduce" and then you'd make the programming API really obscure and difficult to develop for, and then charge a god-given arm and a leg to use it.
They all do the same thing: copy data to nodes, run them, and copy the output back.
Step 8: Benchmark and Go!
I wrote a couple of benchmark programs that basically run the upper.r code 40 times on a large chunk of text I downloaded from Project Gutenberg. The benchmarklocal.sh script runs the test 40 times serially locally on my laptop.
The benchmarkparallel.sh script runs the test 10 times in parallel, then repeats 4 times.
Step 9: Take lots of photos
The sky's the limit. Or rather, the practical limit is my ability to appear socially uninhibited as I bring this suitcase into a conference meeting room, pardon myself as I plug it into the outlet (until I get a battery backup unit), and then run the thing at max speed as I calculate floating point math, and extract long capitalized phrases from anything in the room.
I uploaded the rest of the pictures I took in much higher resolution over on Flickr...
:-)
Enjoy...
I took 10 BeagleBoards and turned a suitcase into a wifi-accessible, on-demand, elastic R computer cluster that runs at 10 Ghz, 40 Gigs of disk, and 1,000 megabits of networking bandwidth. I did this all for less than $2,000, and spent less than 5 hours building it, and now I have a scalable compute resource that is portable, has performance comparable to mid-range and high end servers that cost $15,000-30,000 from IBM or Sun. And better yet, it all runs at 30 Watts. That's less than most of the incandescent light bulbs in my room right now.
I've also made the whole project Open Source, for anyone who wants to replicate it on their own. Personally, I'm going to build another one out of 32 of these suckers, and rent it to the trading firm that bought dozens of Open SciCal's from me in the past couple weeks.
Step 1: Get 10 BeagleBoards
I took 10 BeagleBoards, and used the same standoffs that I use in the Embedded Gadget Pack. I used an offset pattern so they could stack as high as I wanted them to. I built them all the way up to 10, and then decided it wouldn't fit in a suitcase, so I split them up into 2 mini-towers of 5 BeagleBoards each.
Step 2: Buy 3 cheap, low power hubs
I went to Radio Shack (begrudgingly because they sold out to the cell phone man in 2000 and have sucked ever since), since they were the only ones open. I bought 1 wireless router with 5 ethernet ports in the back, and then bought 2 netgear hubs (each had 5 ethernet ports).
Step 3: Wire the "interconnection backplane"
I've been reading old literature about multicore, multi-processor, scalable computer architectures, and they have a funky way of making simple concepts like "network" sound really complex like "Fat Tree Fishbone N-Way Scalable Interconnection Backplane".
Oh so you mean I plugged the two hubs into the wireless router, and then put 4 wires into each of the hubs, and 2 from the router, and connected them to the BeagleBoards with USB-to-Ethernet modules.
Like this:
I have this new mantra that things I read in hefty academic papers are written in language way too fancy for what they're trying to do. I get the sense that this is intentional, to hide the fact that what they researched could be replicated for $2,000 and 5 hours in modern times. I kid, partially. I'm reading papers written in the 1980's and 1990's, when the idea of doing what I just did would have taken a $10,000,000 DARPA grant.
Step 4: Set up the Open SciCal Slave Nodes
Each of the BeagleBoards is running the Open SciCal SD card from Liquidware, with a few notable additions:
-Each card is configured to allow passwordless logins over dropbear SSH
-Each card auto-configures itself to a static IP address
-The cards have a slightly trimmed down set of background apps to make R more responsive
I then replicated the card 10 times, onto each of my SD cards.
Step 5: Build the Power Backbone
This was an easy step conceptually, but a pain to do in an organized manner. So I gave up the organization, and just hacked through it. I took 10 BeagleBoard power connectors from the Liquidware shop (specifically those because they're low wattage). And connected them into two small outlet strips.
I then routed those power cables around and through to each of the 10 Open SciCal BeagleBoard Compute Nodes.
For kicks, I got one of those "kill-a-watt" meters and put it in front of the whole set up, so I could measure how much power the whole thing consumed.
Step 6: Configure the Master
Parallel architecture guys are always labeling nodes "master" and "slave". I think it's some hidden repressed anger at the fact that most of us "nerds" never got picked first for kick-ball and 4-square (the game, not the GPS website) when we were kids. Take that, 2nd grade. Now look who's deciding who's "master" and "slave". Me.
In all seriousness, at this point in the project, I had 10 networked Open SciCal nodes. But no way to issue code to them. So I took out my trusty Ubuntu Linux laptop, and quickly got it to connect to the wireless G router I'd set up to be the master switch for all 10 of the BeagleBoards.
Since the system is running on R, I naturally tried to get some of their default environments running, like Snow, Snowfall, svSockets, and even MPI. But each of those turned out to be serious overkill. Sure, they're easy to use if someone else is installing them for you and you don't have to think about it, but they didn't really get the job done in the amount of time I was willing to dedicate, so I wrote my own scripts.
Here are all of the programs I wrote, in one "app" on the "Open Source App Store".
Step 7: Write Elastic R Programs
I was hired by a company a couple months ago to write data mining algorithms to run on the Open SciCal. Most of them were top secret, but a few were pretty elementary. For instance, one function that is used often in text data mining is a function to extract all capitalized phrases. For instance, Amazon uses this on their website to summarize books with a few phrases.
Here's the R code that extracts the indexed location of any capitalized word in a piece of text:
x=readLines(file("data.txt"));
y=(unlist(lapply(x,function(x){lapply(x,function(x){strsplit(x," ")})})));
z=y[y!=""];
out=which(lapply(z,function(x){grep("[A-Z]",unlist(strsplit(x[1],""))[1],value=FALSE,invert=FALSE)})==1);
write.csv(out,file="out.txt")
This is a piece of code that you'd often want to run against 1,000's of pieces of text at a time, to extract important pieces of information. I wrote this into a program called "upper.r".
I then wrote some "administrative" functions for my homemade Elastic R Beowulf cluster - you can download them here:
"esh" - "elastic shell" - this runs a command on all of the slave nodes, and kicks back the output
For instance: esh "uname -a"
"ecp" - "elastic copy" - this copies a file to the home/root/ directory of each of the slave nodes
"epush" - "elastic data replicate push" - this takes a set of data files in the data/ folder called "1.txt" "2.txt" "3.txt" etc. all the way up to "10.txt" and copies them over to each node as /home/root/data.txt. This is important if you want to parallelize different data across to each of the nodes.
"epull" - "elastic data extract pull" - this does the inverse of "epush" in that it pulls a single file called /home/root/out.txt off each of the nodes, and renames them locally into the "out/" folder as "1.txt" "2.txt" "3.txt" etc. according to which node it came off
A typical session would look something like this:
esh "uname -a"
ecp upper.r
epush data.txt
esh "R BATCH < href="http://en.wikipedia.org/wiki/MapReduce">Map/Reduce". If you wrote about parallel computing in the 1980's, you would call it "Distribute/Evaluate/Collect". If you worked at Wolfram Media, you'd call it "ParallelDistribute/ParallelMap". Or if you hacked on the Cray, you'd call it "LoadVec/ParVec/PopVec". At NVIDIA you'd probably call this "CUDALoad/CUDAExecute". Or if you were the CEO of Amazon, I supposed you'd call it "Elastic Cloud Map Reduce" and then you'd make the programming API really obscure and difficult to develop for, and then charge a god-given arm and a leg to use it.
They all do the same thing: copy data to nodes, run them, and copy the output back.
Step 8: Benchmark and Go!
I wrote a couple of benchmark programs that basically run the upper.r code 40 times on a large chunk of text I downloaded from Project Gutenberg. The benchmarklocal.sh script runs the test 40 times serially locally on my laptop.
The benchmarkparallel.sh script runs the test 10 times in parallel, then repeats 4 times.
#!/bin/bash
./ecp data.txt
./ecp upper.r
./esh "R BATCH --no-save <>
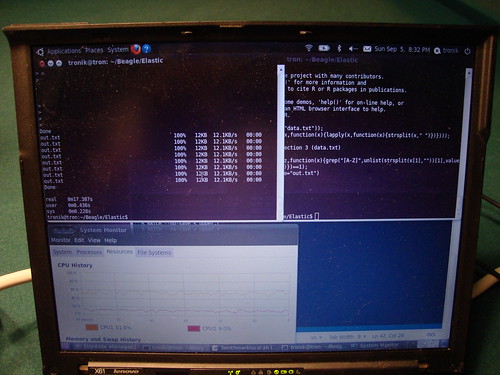
The results are surprising to me, at least. The punchline is that, on average, the Dual-Core Intel chip takes ~30-35 seconds to complete the tests, while the BeagleBoard Elastic R Beowulf Cluster takes around ~20 seconds.
benchmarkparallel.sh is faster than my top-of-the-line $4,500 Lenovo work laptop running benchmarklocal.sh. Now there are always going to be skeptics saying, I could have optimized this or that, but that's not the point. I built it much faster than I could have normally...
Step 9: Take lots of photos
The sky's the limit. Or rather, the practical limit is my ability to appear socially uninhibited as I bring this suitcase into a conference meeting room, pardon myself as I plug it into the outlet (until I get a battery backup unit), and then run the thing at max speed as I calculate floating point math, and extract long capitalized phrases from anything in the room.
I uploaded the rest of the pictures I took in much higher resolution over on Flickr...
:-)
Enjoy...
Labels:
Liquidware
Sunday, September 5, 2010
If the Old Spice Man were an Arduino
I worked fairly late last night on one of my projects, so I'm in a silly mood as I type this. Justin just mentioned to me that he built some more Illuminato Genesis boards, and that I should mention that they're now in stock for the first time in months. But that would be boring, so I figured I'd "spice" up the public service announcement... and Chris and I have had an inside joke with Chris that the Illuminato Genesis is the Old Spice Man of Arduinos :-)
The Illuminato Genesis has a lot in common with the Old Spice man:
It's ripped - with 42 I/O pins
It's built - by hand
It's tall - with 64k of memory
And it's suave - with custom LED's
So naturally...
Look at your Arduino.
Now back at me.
Now back at your Arduino
Now back to me.
Sadly, he isn't me.
But if he had 42 I/O pins, and had twice the memory, he could function like he's me.
Look down.
Back up.
Where are you? Your in a lab with wires.
With the Arduino your Arduino could look like.
What's in your hand?
Back at me.
It's an oyster (or 2 shells) with two USB mini B connector cables to interface that thing you love.
Look again.
The cables are now a TouchShield Slide!
Anything is possible when your Arduino is an Illuminato Genesis and not a Duemilanove.
I'm on a horse.
You have no idea how hard it is to find a horse these days. :-)
By now, almost the whole world knows about the "Old Spice Man":
The Illuminato Genesis has a lot in common with the Old Spice man:
It's ripped - with 42 I/O pins
It's built - by hand
It's tall - with 64k of memory
And it's suave - with custom LED's
So naturally...
Look at your Arduino.
Now back at me.
Now back at your Arduino
Now back to me.
Sadly, he isn't me.
But if he had 42 I/O pins, and had twice the memory, he could function like he's me.
Look down.
Back up.
Where are you? Your in a lab with wires.
With the Arduino your Arduino could look like.
What's in your hand?
Back at me.
It's an oyster (or 2 shells) with two USB mini B connector cables to interface that thing you love.
Look again.
The cables are now a TouchShield Slide!
Anything is possible when your Arduino is an Illuminato Genesis and not a Duemilanove.
I'm on a horse.
You have no idea how hard it is to find a horse these days. :-)
By now, almost the whole world knows about the "Old Spice Man":
Labels:
Liquidware
Subscribe to:
Posts (Atom)